🤖 3: AI Chatbot Setup
Welcome to the next step of your Testus Patronus journey! In this exercise, you'll connect your RAG pipeline to your chatbot, enabling it to answer questions using your uploaded knowledge base.
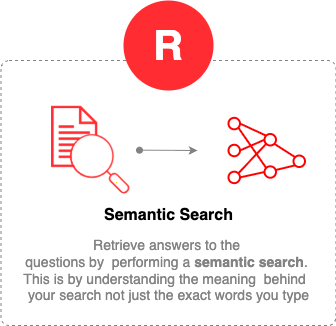
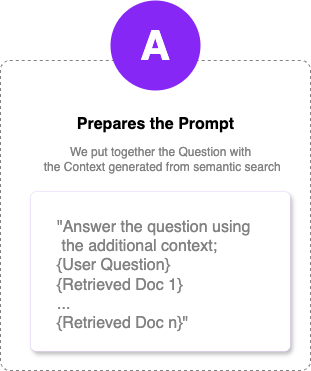
🧩 What You'll Do
🛠️ Step 1: Start a New Chatflow
Click Studio in the left sidebar, then Create → Create from Blank.
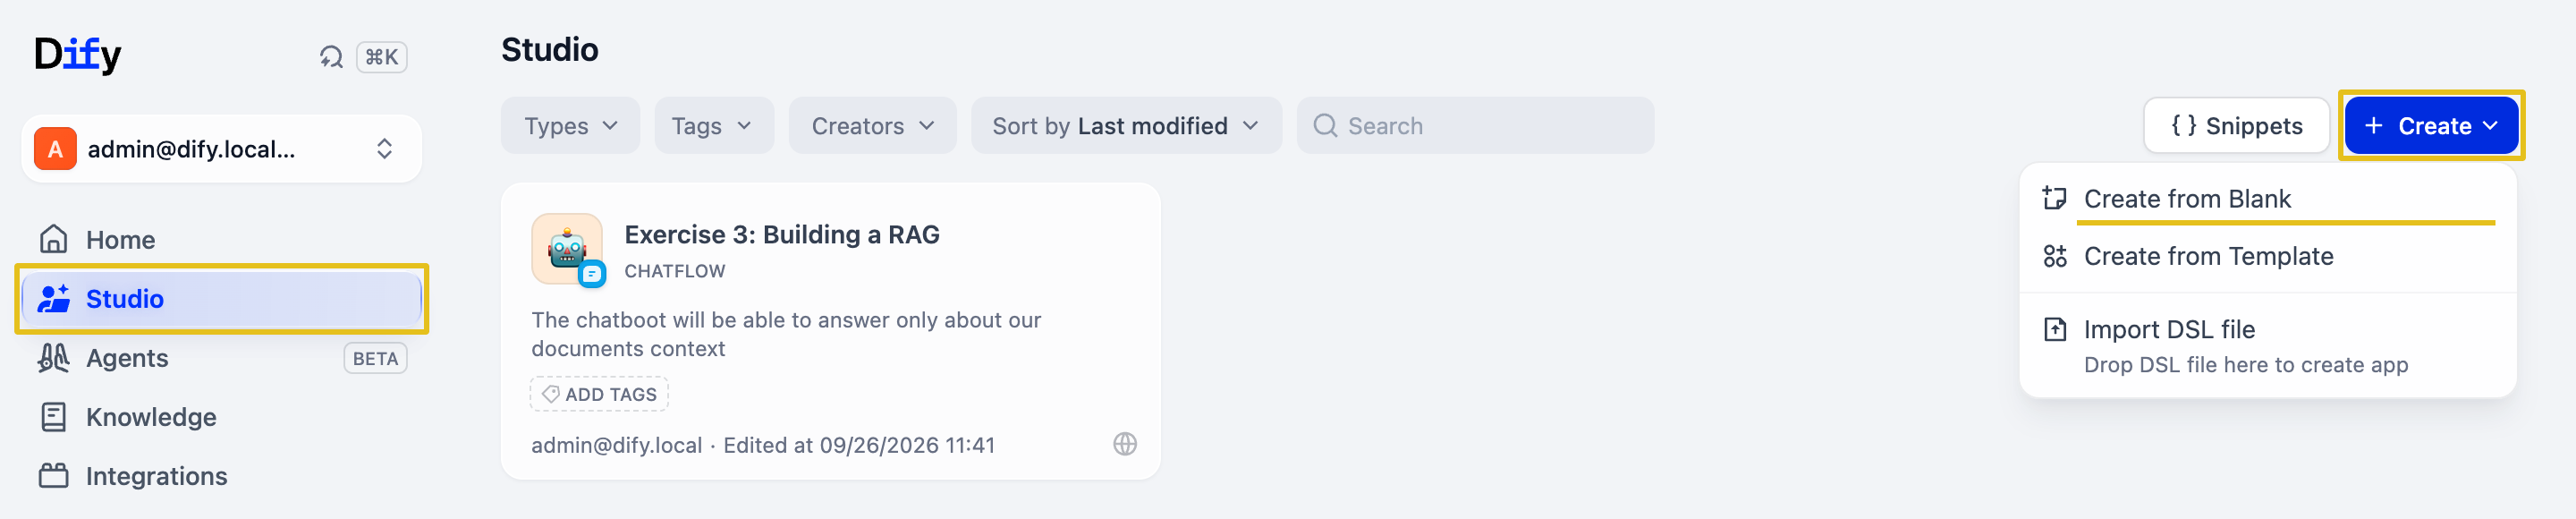 Studio → Create → Create from Blank
Select Chatflow, give it a meaningful name and description, and click Create.
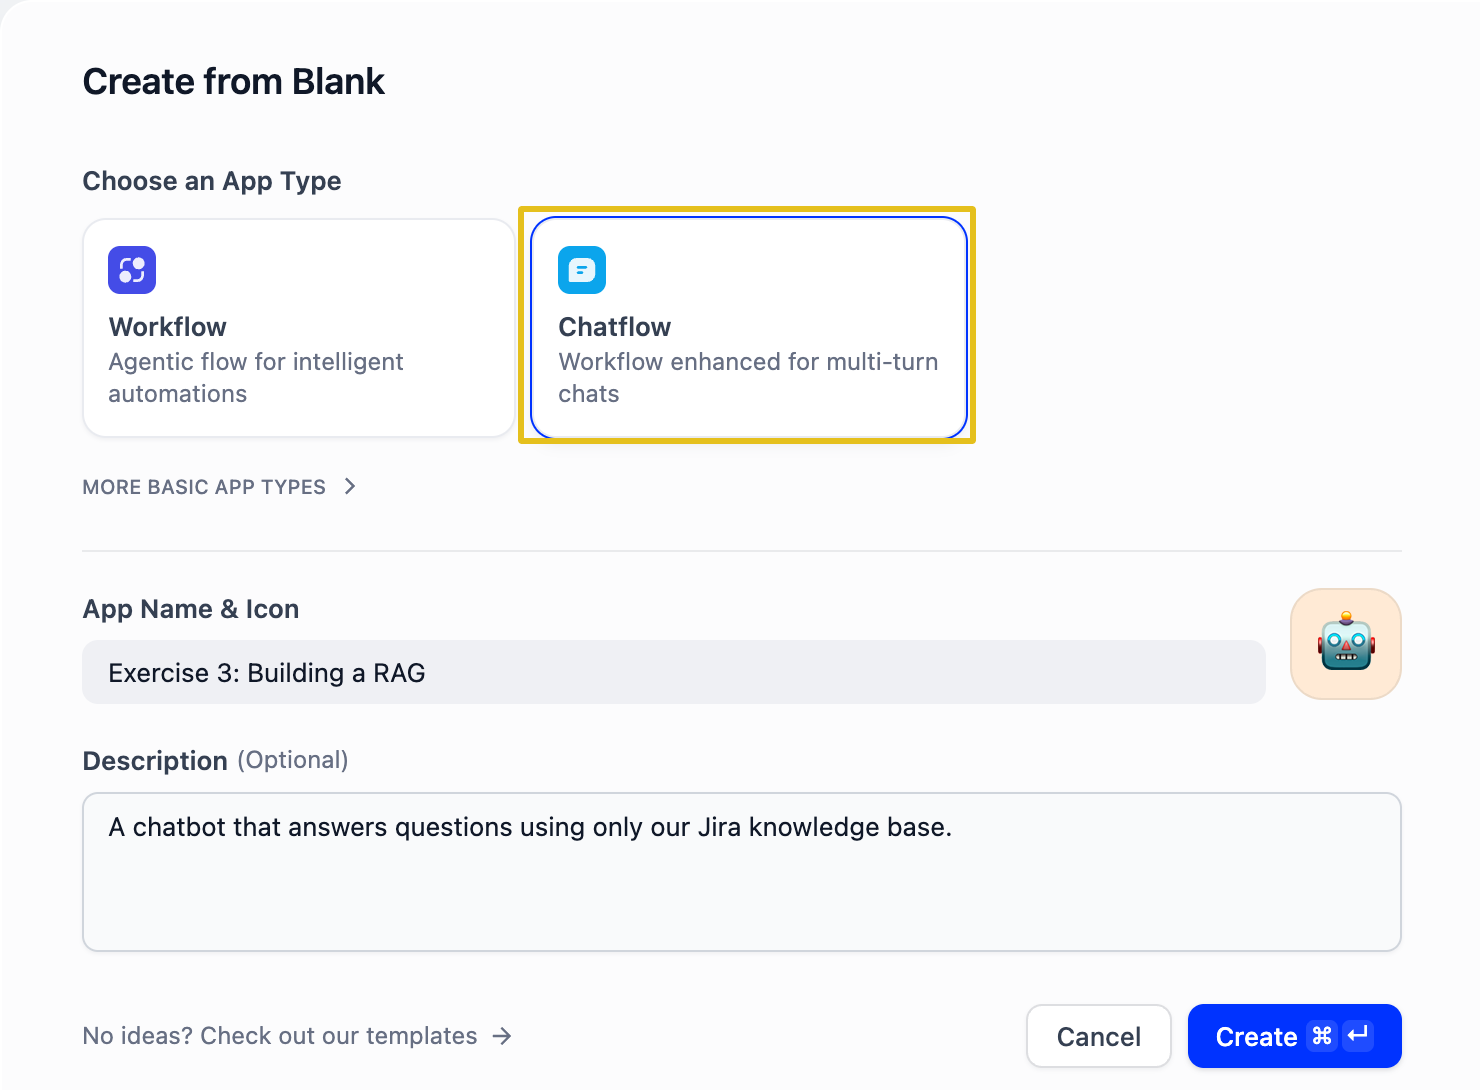 Chatflow selected, with name and description
A new Chatflow already contains User Input → LLM → Answer. Open the LLM node and select gpt-35-turbo-16k as the model. Then write a SYSTEM prompt, and use the {x} button (or type
{) to insert the Context block.The user's question is already in the USER message (
User Input / query), so the SYSTEM prompt only needs your instructions and the context.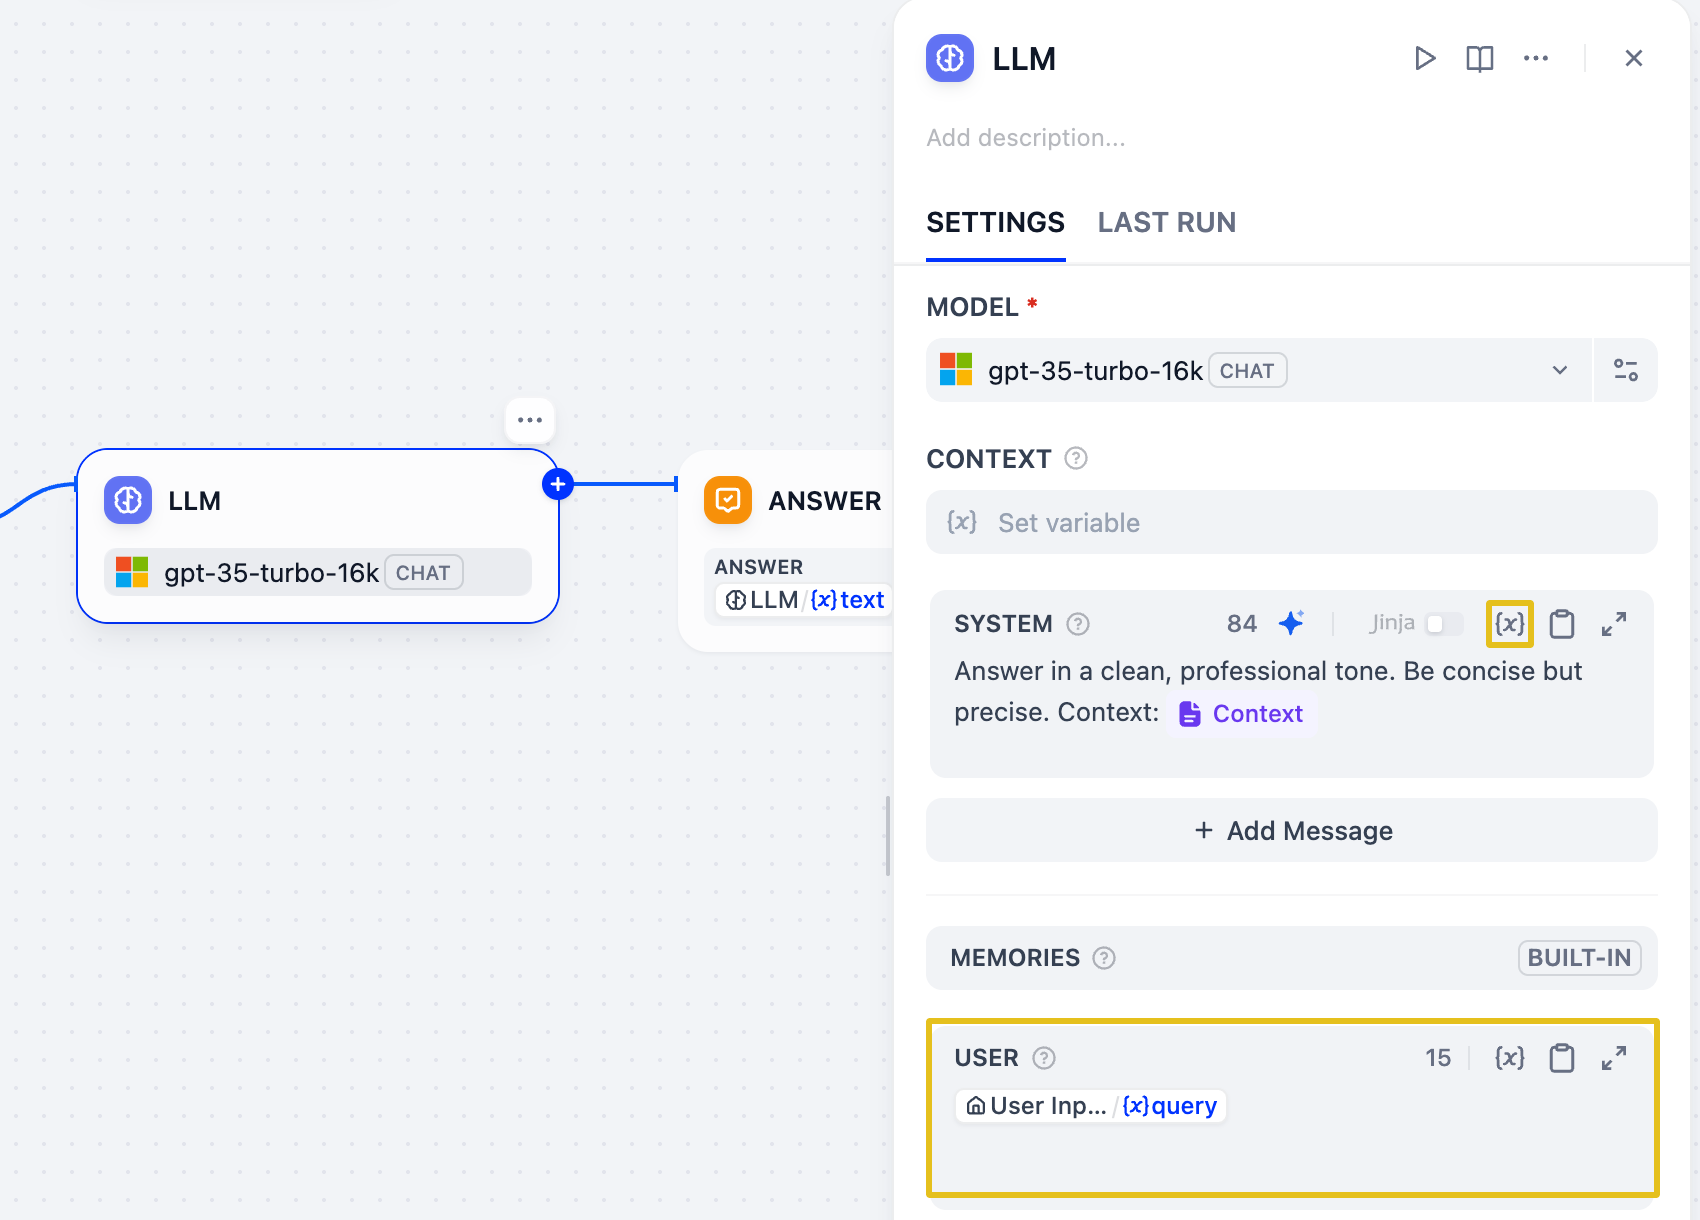 LLM node: SYSTEM prompt with Context, USER message with query
Click Preview and ask a question. Expand Workflow Process above the answer to see each node that ran, with its duration and token count.
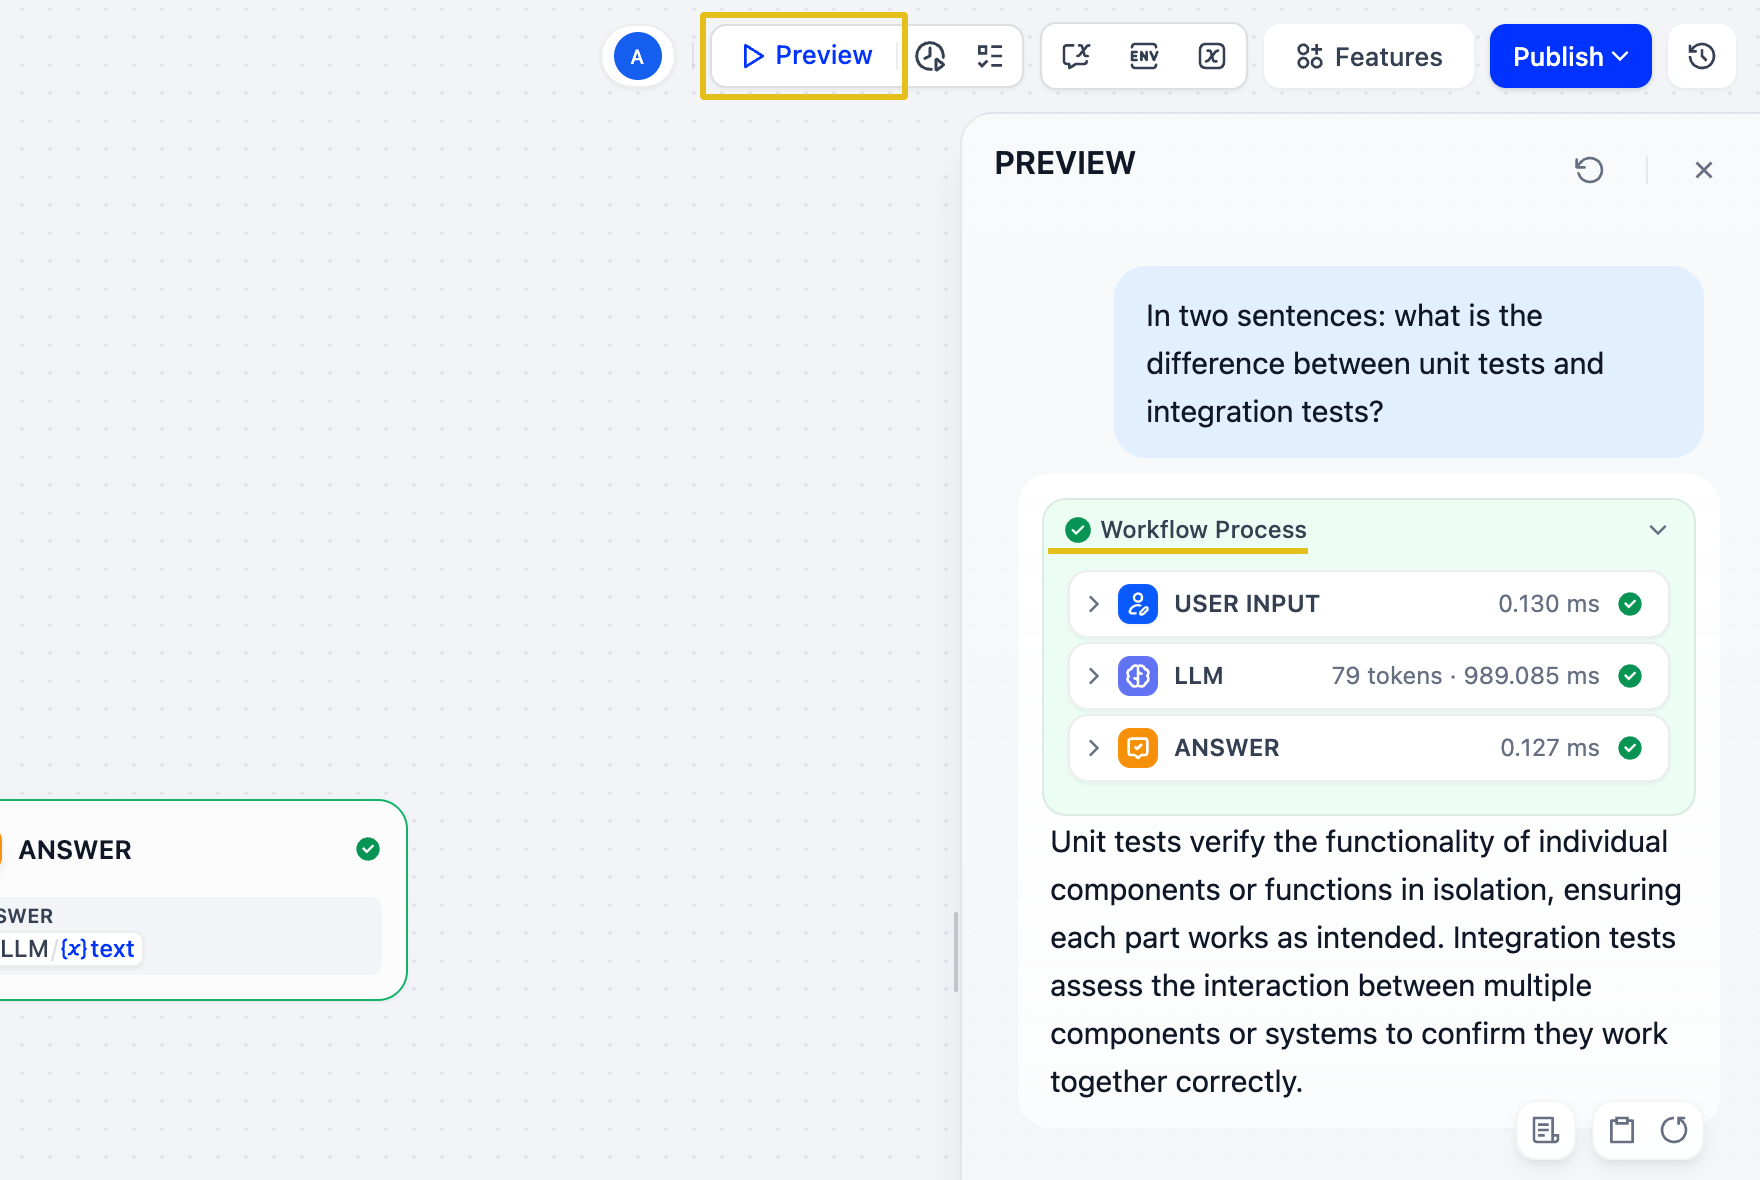 Preview with the Workflow Process expanded
🛠️ Step 2: Add a Knowledge Retrieval Node
Hover the connection between User Input and LLM, click the + that appears, and choose Knowledge Retrieval.
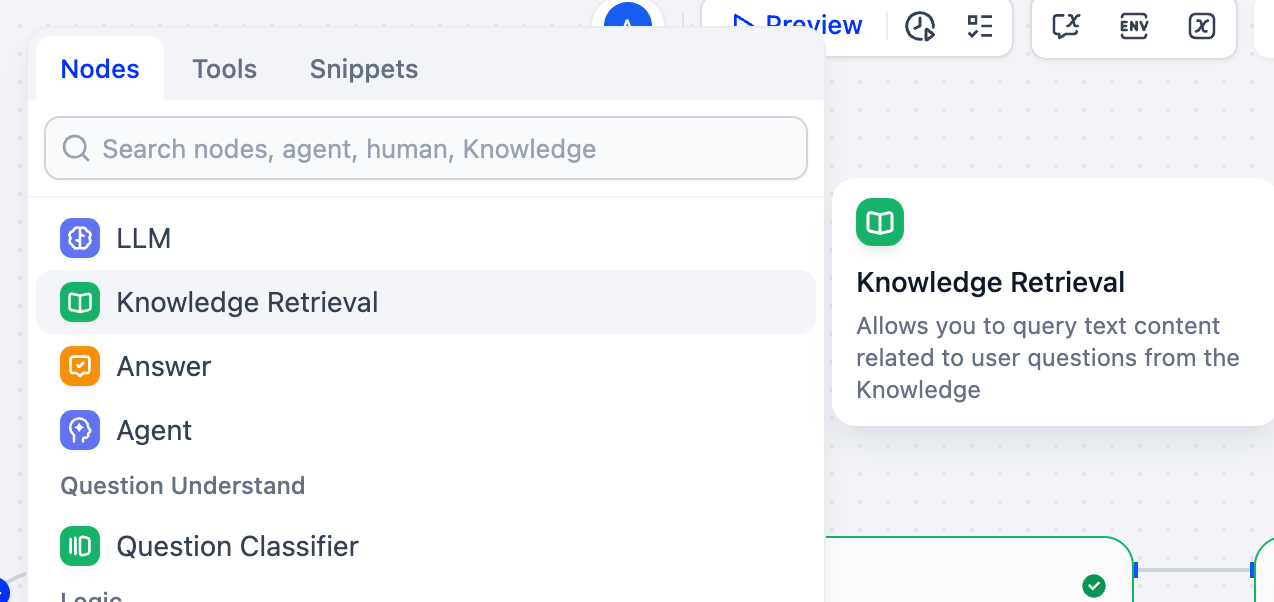 The node picker: Knowledge Retrieval queries your knowledge base with the user's question
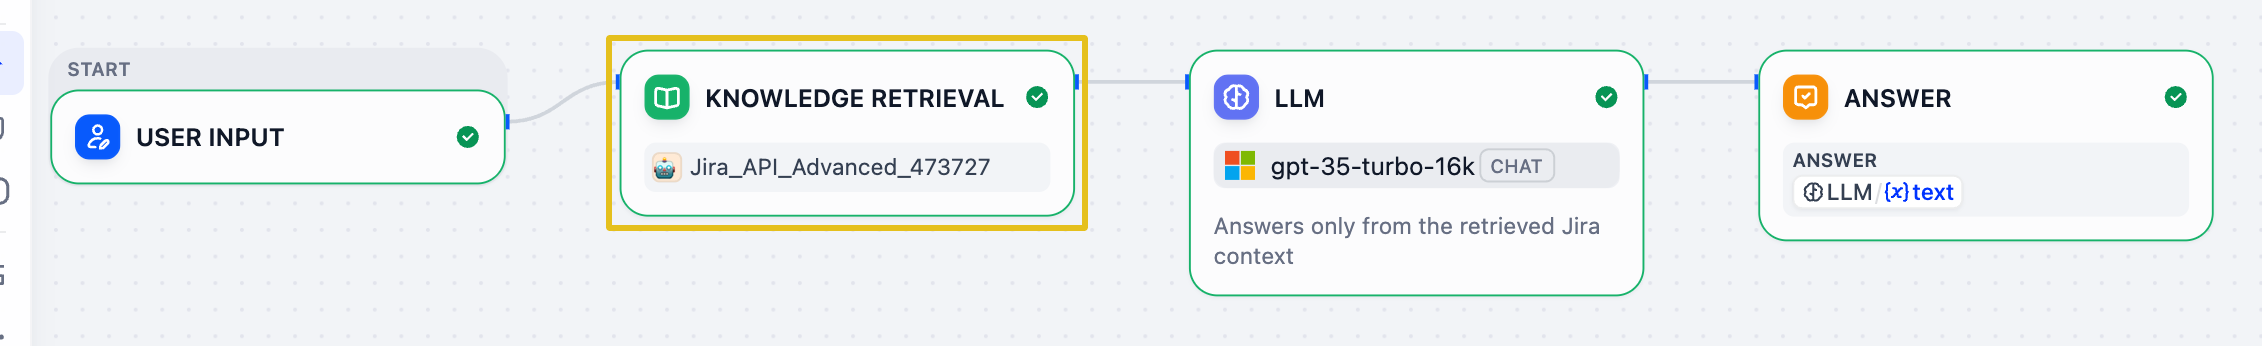 The Chatflow now runs User Input → Knowledge Retrieval → LLM → Answer
In the Knowledge Retrieval panel, Query Text is already set to
sys.query. Click the + next to Knowledge to add a knowledge base.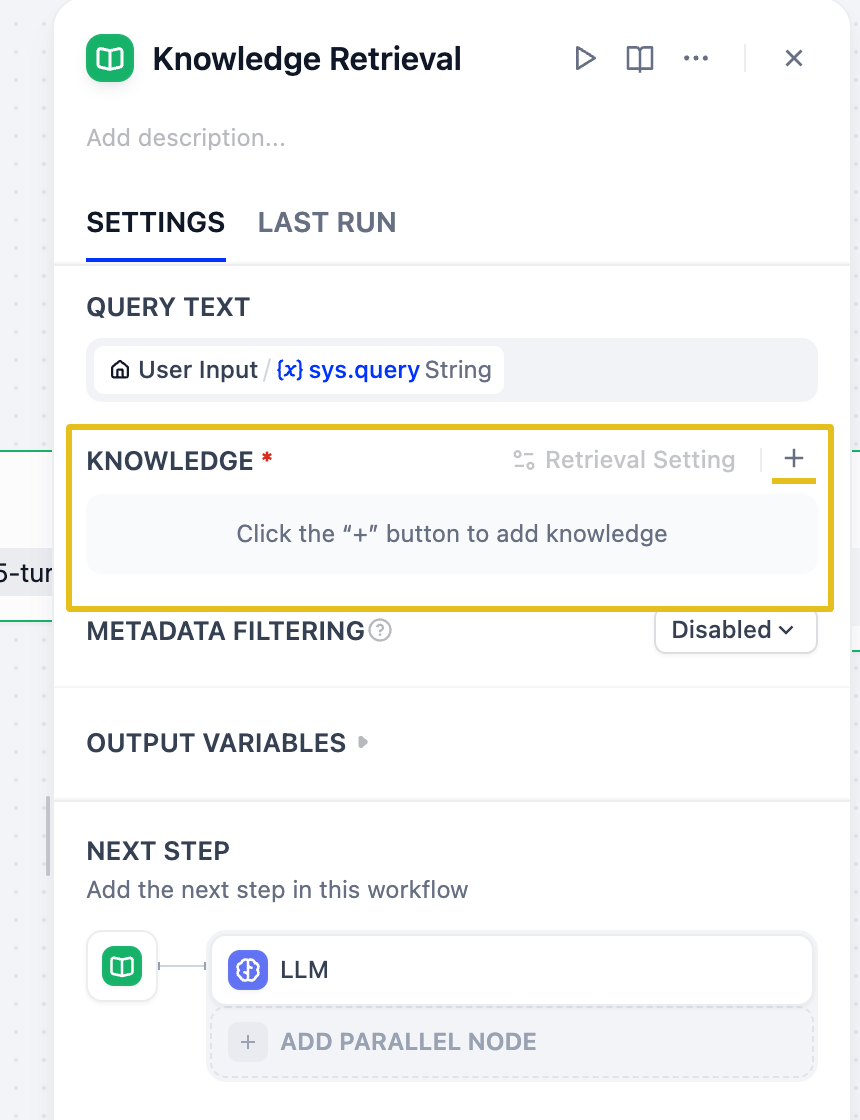 Add knowledge with the + button
Select the knowledge base you want the chatbot to use and click Add:
- If you completed Exercise 2.1, select
Jira_API_Advanced_*(recommended) orJira_API_Basic_*. - If you only did the manual upload, select your manually created knowledge base.
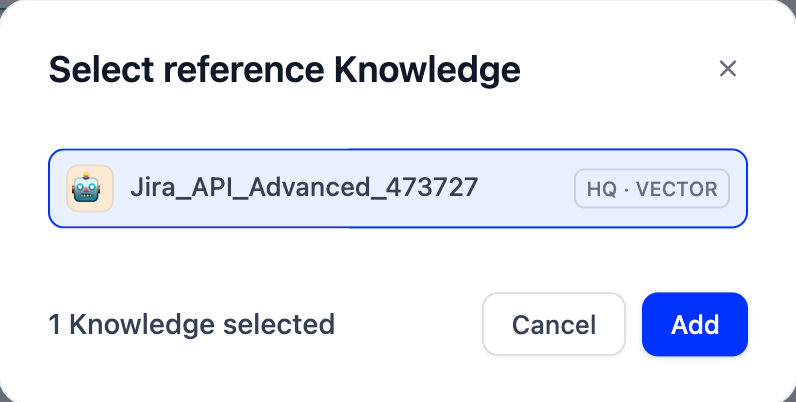 Selecting a knowledge base
- If you completed Exercise 2.1, select
Look at the Metadata Filtering options: Disabled, Automatic, and Manual. Keep it Disabled for now. Filtering on an exact Jira key needs the key extracted from the question first, which you'll add in Exercise 4.
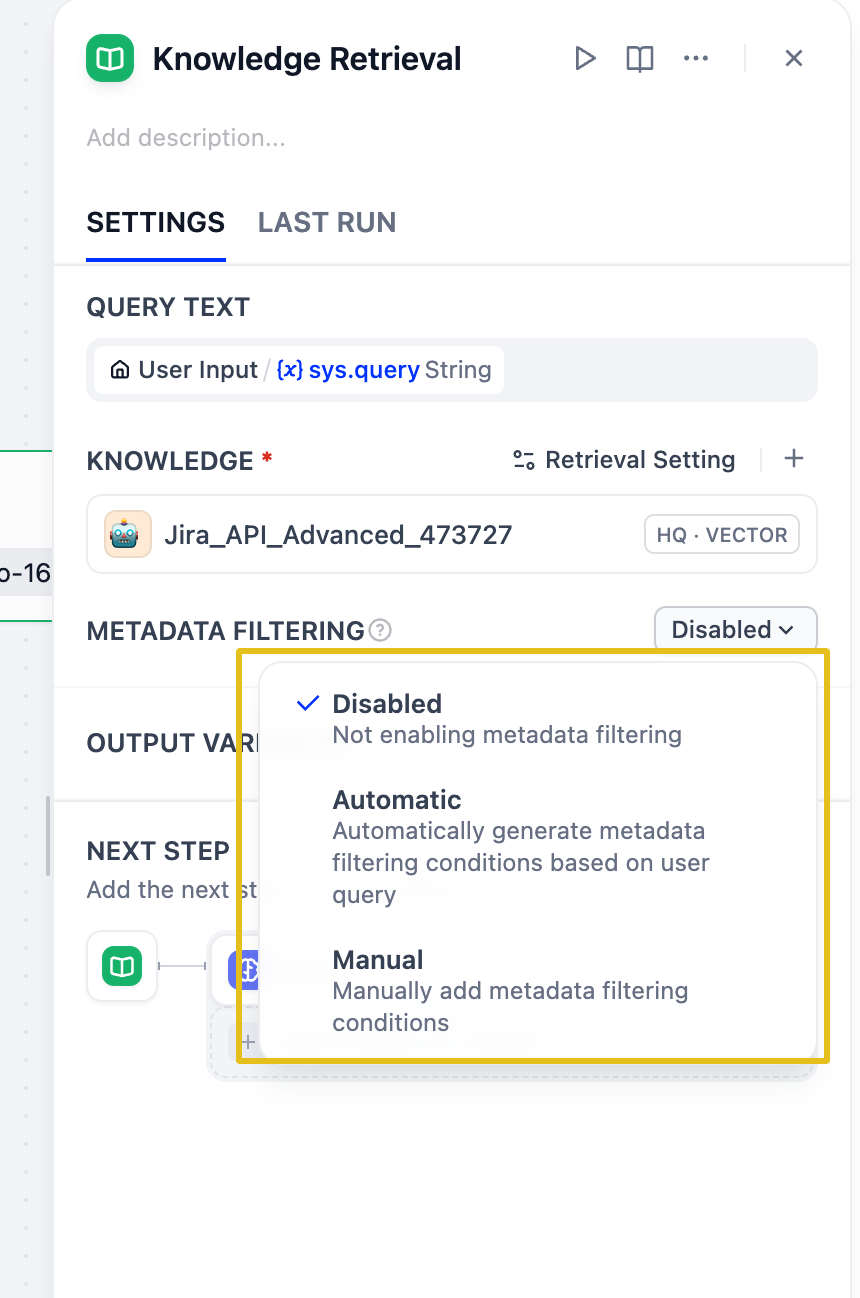 Metadata filtering options
Tip: The Knowledge Retrieval node finds the most relevant chunks in your knowledge base. The LLM only sees them if you pass them in as context, which is the next step.
Oops! But does it really work already? Ask What is this issue about: Jira Issue: REST-259? in Preview:
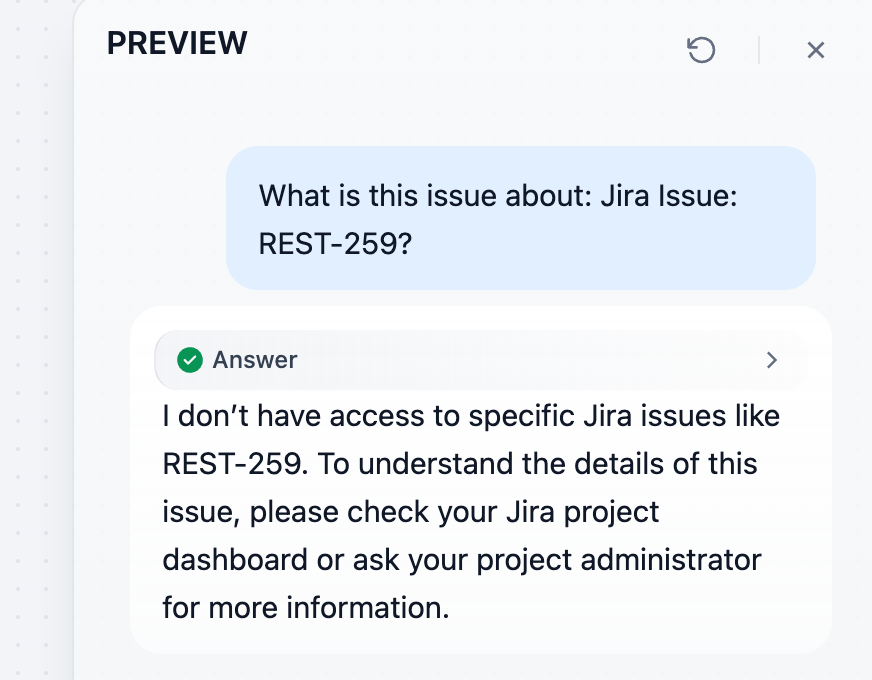
❌
Failure: The retrieval node runs, but its results never reach the LLM.
The model answers from its own knowledge and says it can't see your Jira issues.
🛠️ Step 3: Connect the Retriever to the LLM
Open the LLM node, click Set variable under Context, and choose Knowledge Retrieval → result.
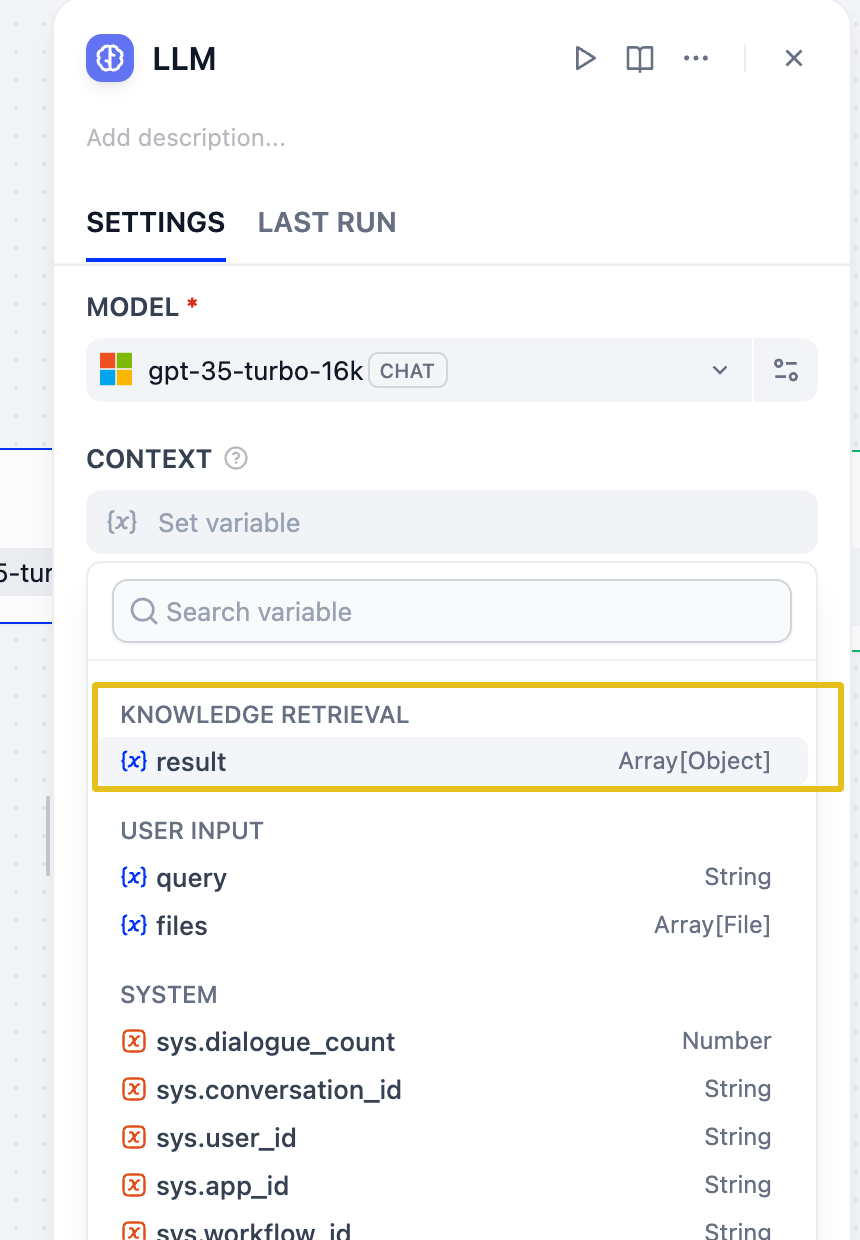 Bind Knowledge Retrieval → result to the LLM's Context
Ask the same question again.
✅ Success: The chatbot now answers from the retrieved Jira issue and lists its Citations.
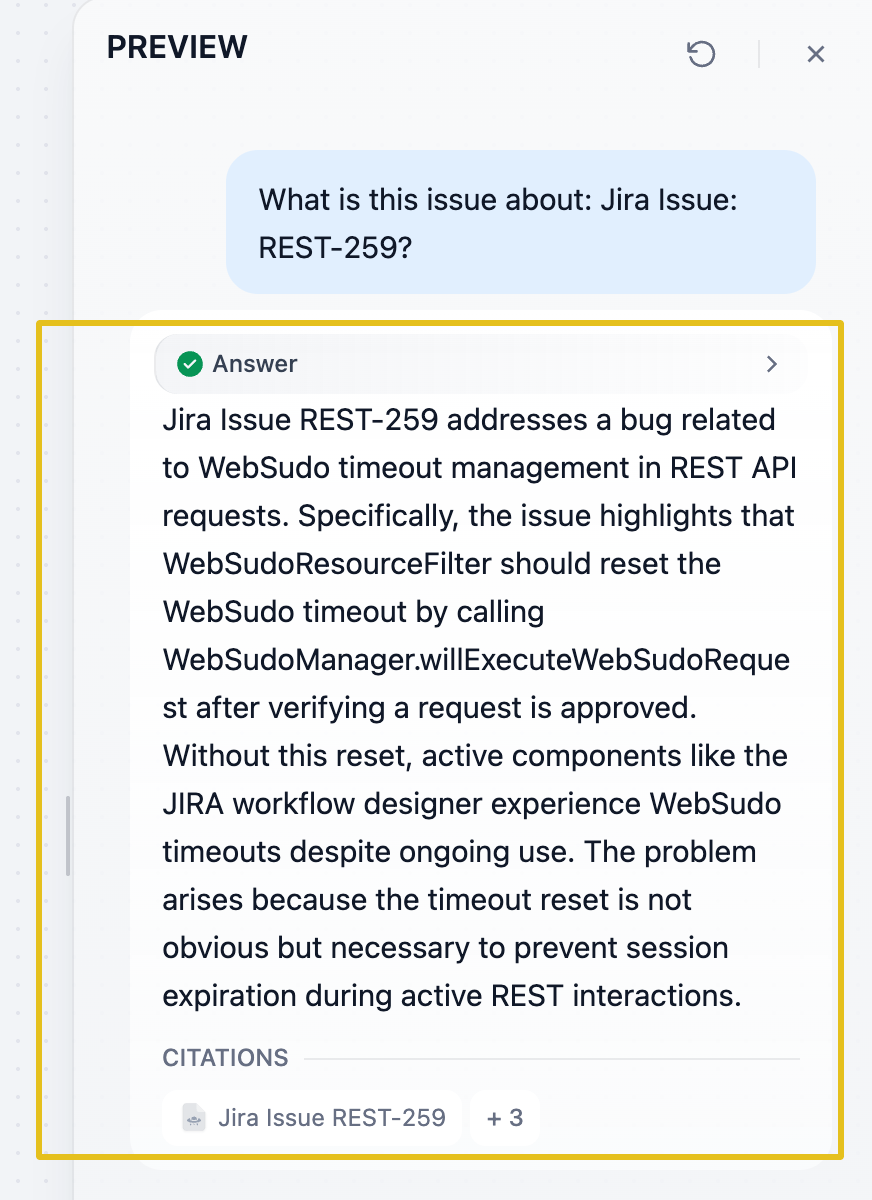 A grounded answer with citations
🛠️ Step 4: Test Your RAG Chatbot
- What is the main focus of the REST module?
- Describe the issue REST-259.
- List features related to webhook support.
Check the answer against its sources
Run this risk-oriented query:
Which Jira issue creates a backward-compatibility risk around unknown JSON properties, and what should we test?
The answer passes only if it names REST-266, explains the compatibility risk, gives test ideas supported by the retrieved context, and shows source citations.
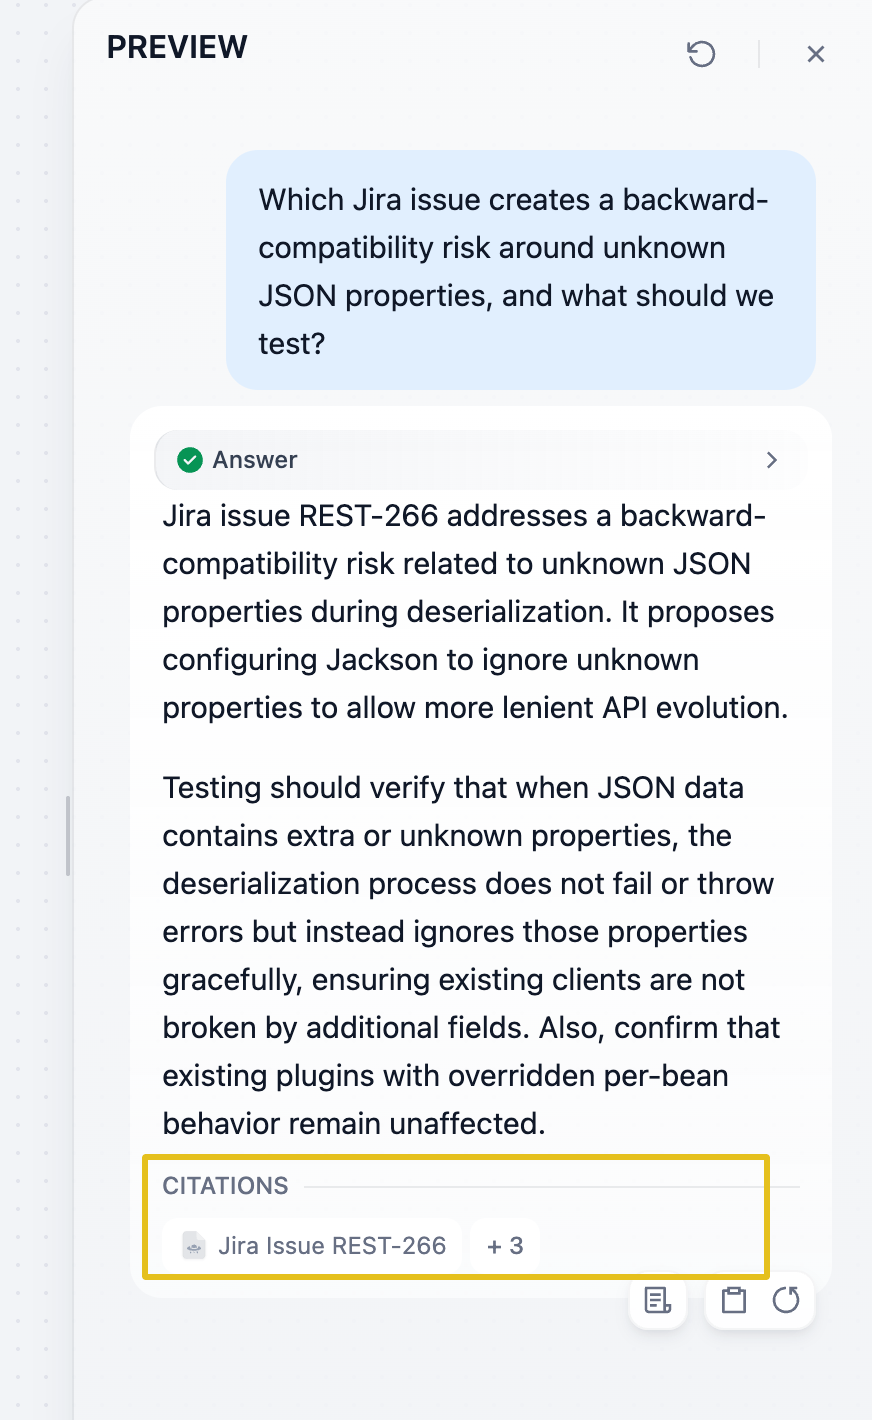
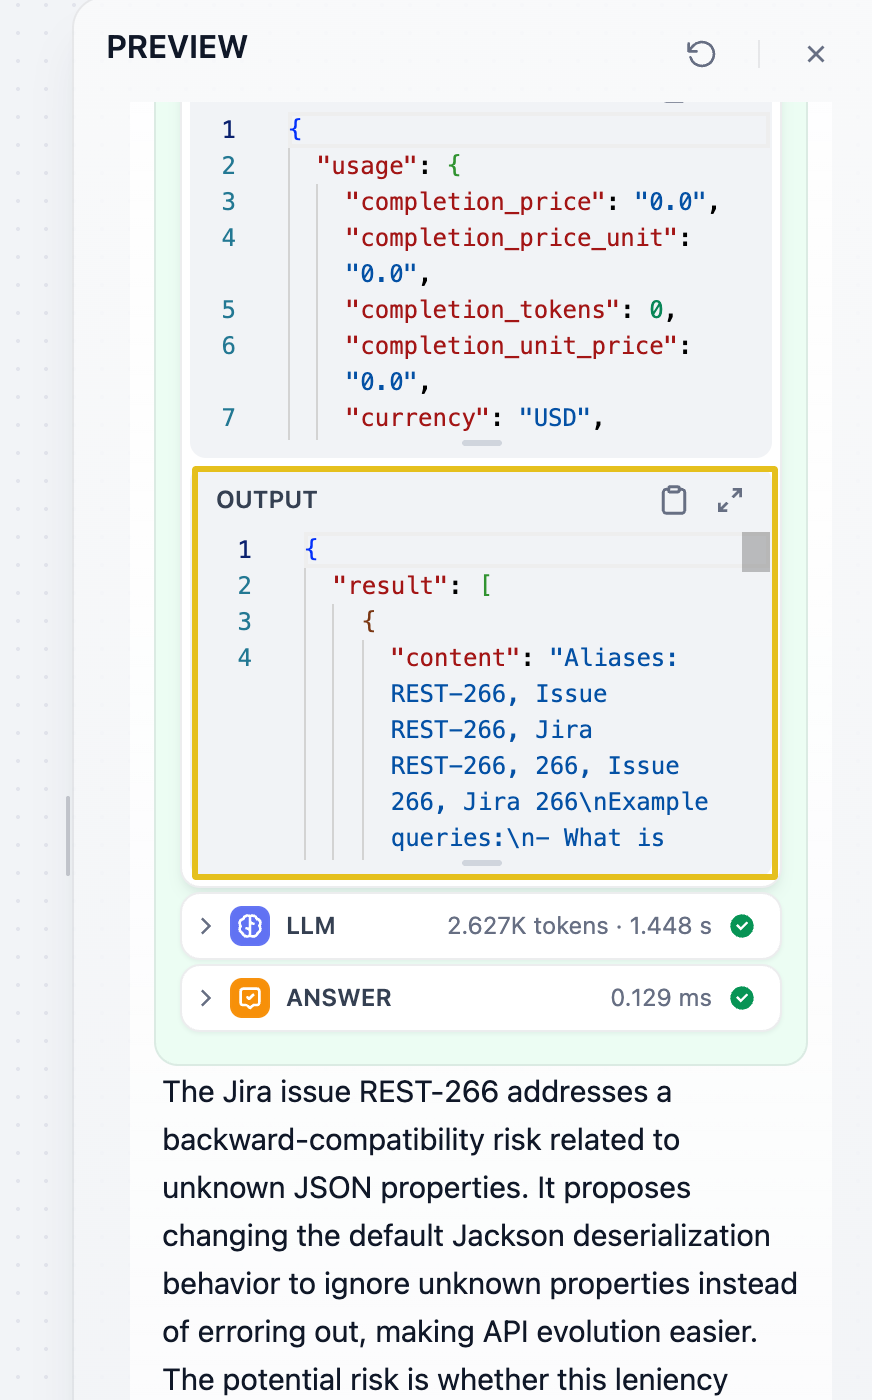
Now expand Workflow Process and click the Knowledge Retrieval step. INPUT shows the query that was searched:
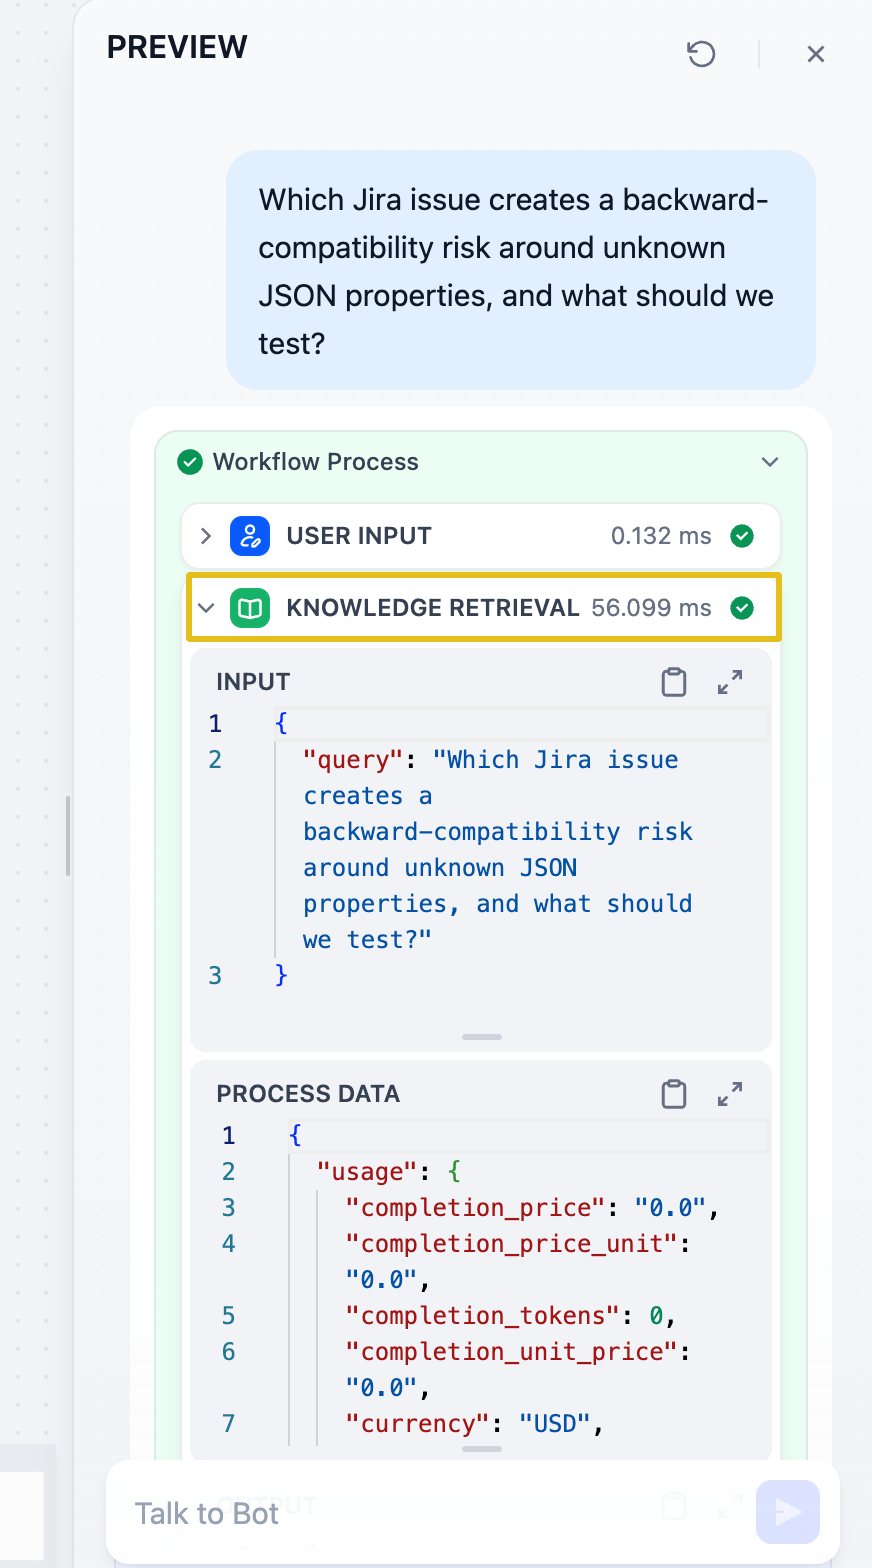
Scroll down to OUTPUT. It lists the chunks that were retrieved and passed to the LLM. Here the top chunk is REST-266, including the aliases and example questions that advanced ingestion added. Checking what was retrieved is stronger evidence than an answer that merely sounds right.
🛠️ Step 5: Augmenting Your Prompt
1. Current Behaviour: Out-of-Scope Answers
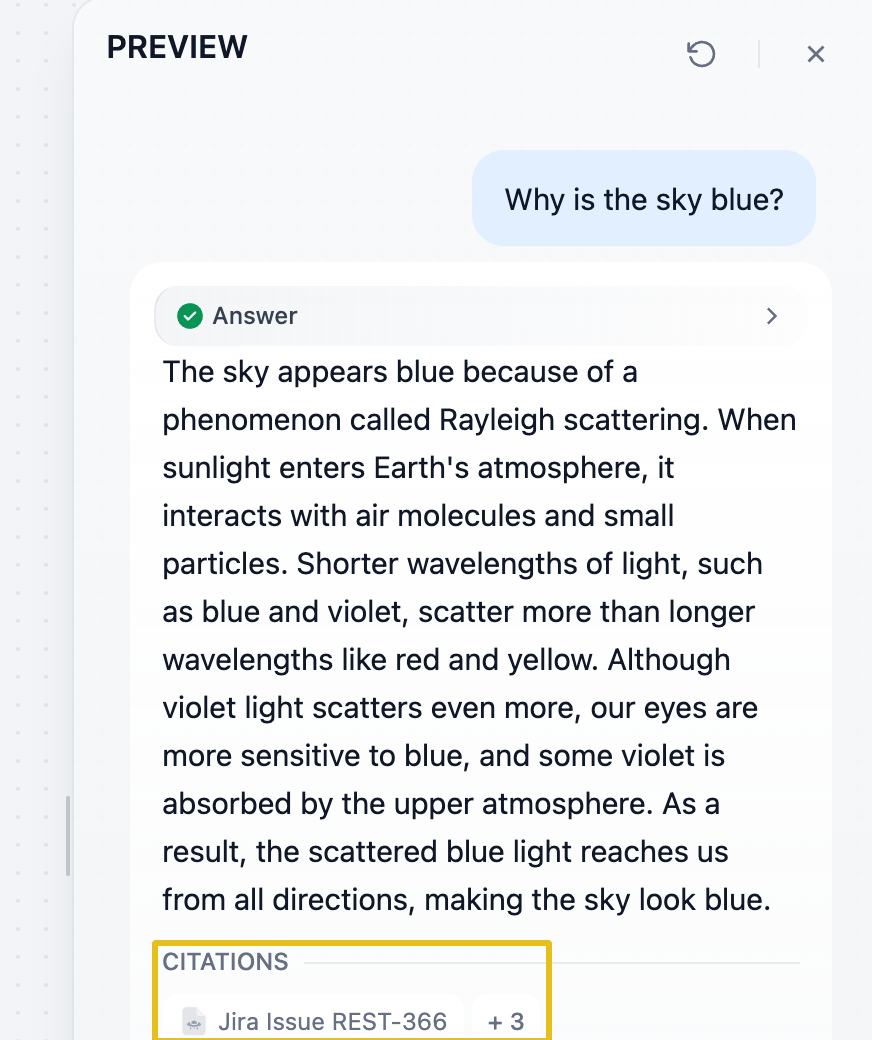
Ask something that has nothing to do with your project: Why is the sky blue?
⚠️
Current Behaviour: The chatbot happily explains Rayleigh scattering, and even shows Jira citations that have nothing to do with the answer.
Two things go wrong: the prompt doesn't tell the LLM to stick to the context, and the retriever always returns its top chunks, even when none are relevant.
2. Preventing Hallucination and Out-of-Scope Answers
🔍 Fix the prompt: Tell the LLM to answer only from the provided context, and give it an exact reply to use when the context doesn't help.
Copy-paste Prompt Example
Answer in a clean, professional tone. Be concise but precise.
Only answer questions using the information provided in the context below.
If the context does not contain relevant information to answer the user's question, reply exactly:
"I'm sorry, I can't find relevant information in the project documentation to answer that."

Context:
{{#context#}}
Paste it into the LLM's SYSTEM prompt, replacing what's there. Dify turns {{#context#}} into the Context block. Ask again:
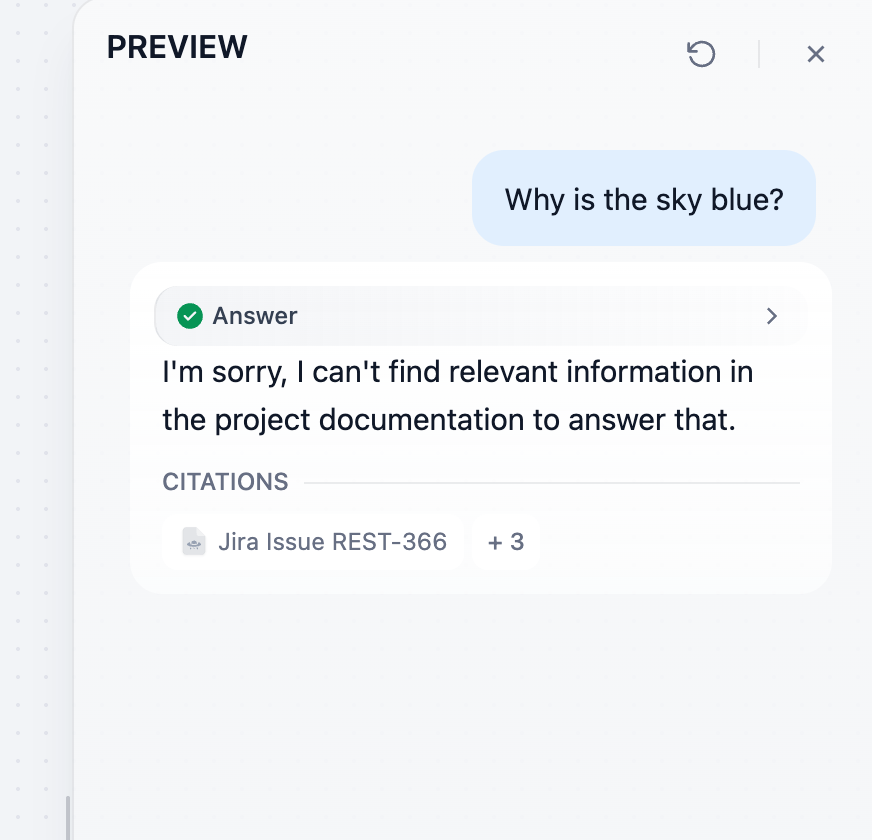
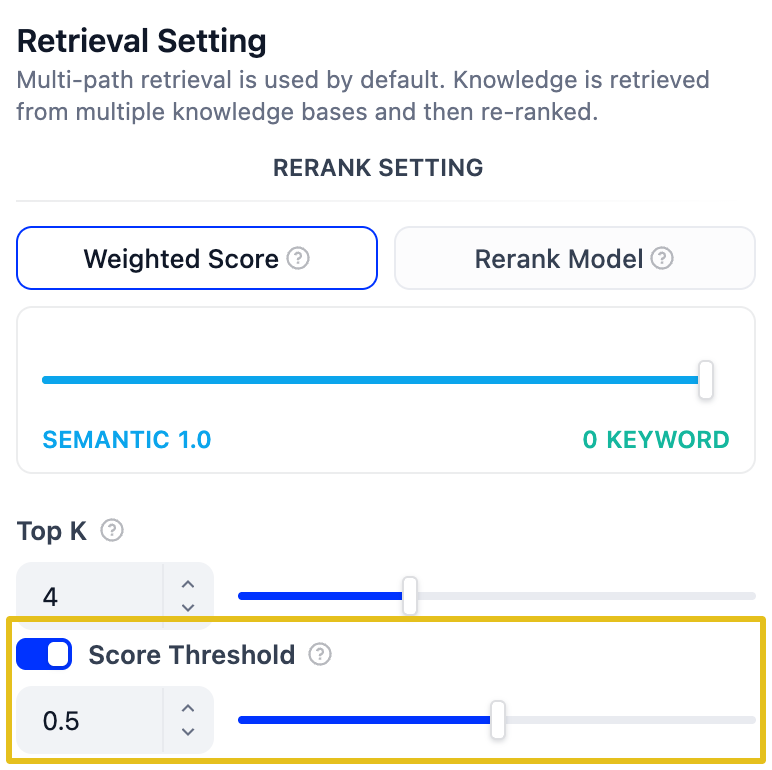
The answer is fixed, but the unrelated citations are still there, because the retriever still returns chunks. To fix that too, open the Knowledge Retrieval node, click Retrieval Setting, and turn on Score Threshold at 0.5. Chunks scoring below the threshold are dropped. Out-of-scope questions then retrieve nothing, while REST-259 and REST-266 still return their issues.
3. Improving Our Prompt and Results
✨ Improving Our Prompt: Refine your prompt to be more specific and structured for your use case. For example, you can:
- Define the assistant's role (e.g., "You are a software testing assistant helping engineers understand Jira issues, project documentation, and related work.")
- Describe what the context chunks contain (a Jira key and aliases, summary, type, status, assignee, and description)
- Ask the assistant to organise key information, highlight relevant fields, clarify technical areas, and explain what it means for testing
- Clearly state how to handle missing information (e.g., mention what's known and what isn't)
This level of detail helps the LLM provide more accurate, relevant, and actionable answers.
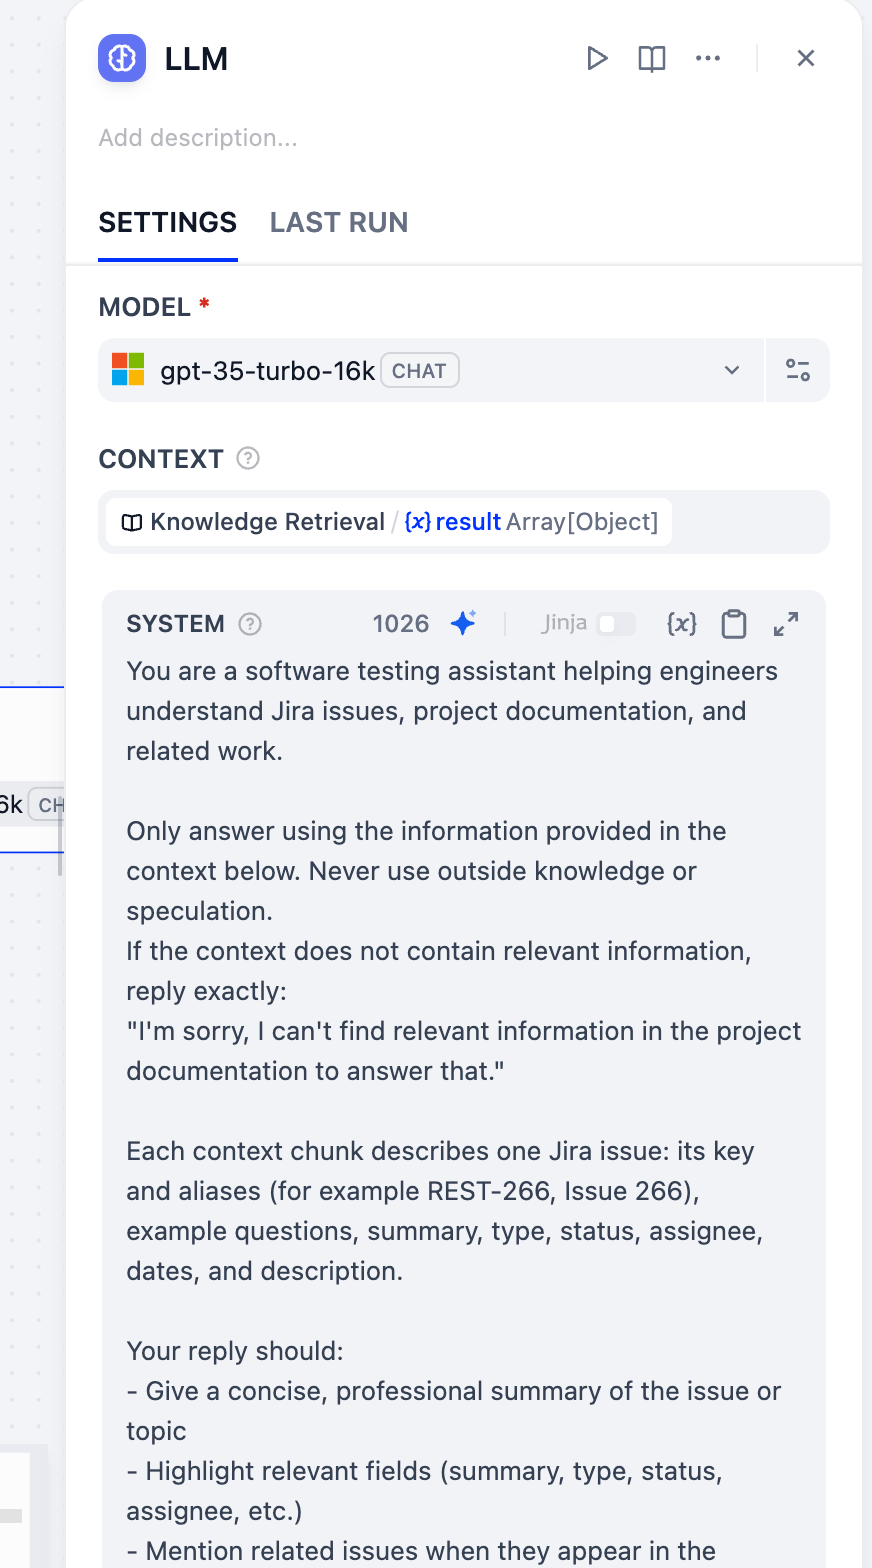
Sample Prompt for Students
You are a software testing assistant helping engineers understand Jira issues, project documentation, and related work.

Only answer using the information provided in the context below. Never use outside knowledge or speculation.
If the context does not contain relevant information, reply exactly:
"I'm sorry, I can't find relevant information in the project documentation to answer that."

Each context chunk describes one Jira issue: its key and aliases (for example REST-266, Issue 266), example questions, summary, type, status, assignee, dates, and description.

Your reply should:
- Give a concise, professional summary of the issue or topic
- Highlight relevant fields (summary, type, status, assignee, etc.)
- Mention related issues when they appear in the context
- Clarify technical areas (for example endpoints, APIs, modules)
- Explain the relevance for testing (for example new test cases, regression risk, feature readiness)

If information is missing, say what is known and what isn't.

Context:
{{#context#}}
✨ Optional: Add a Conversation Opener
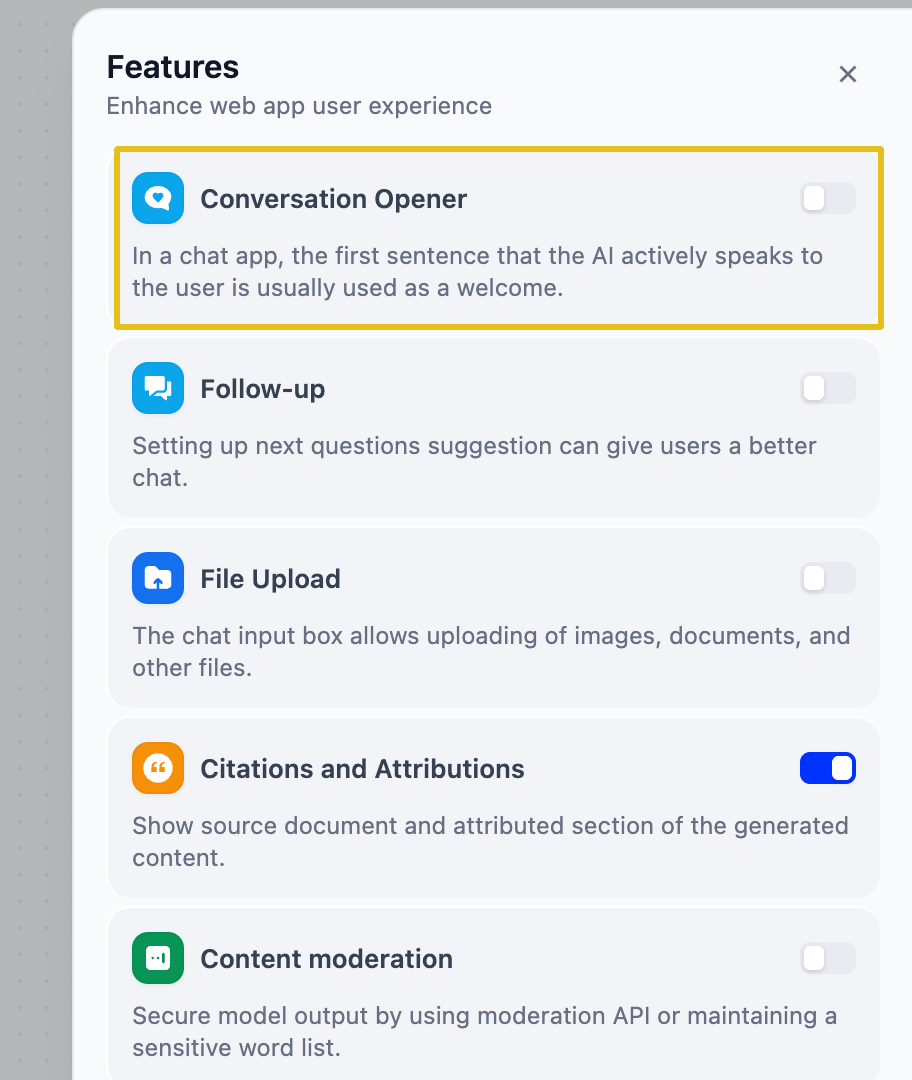
Make your chatbot more welcoming with a Conversation Opener and suggested questions
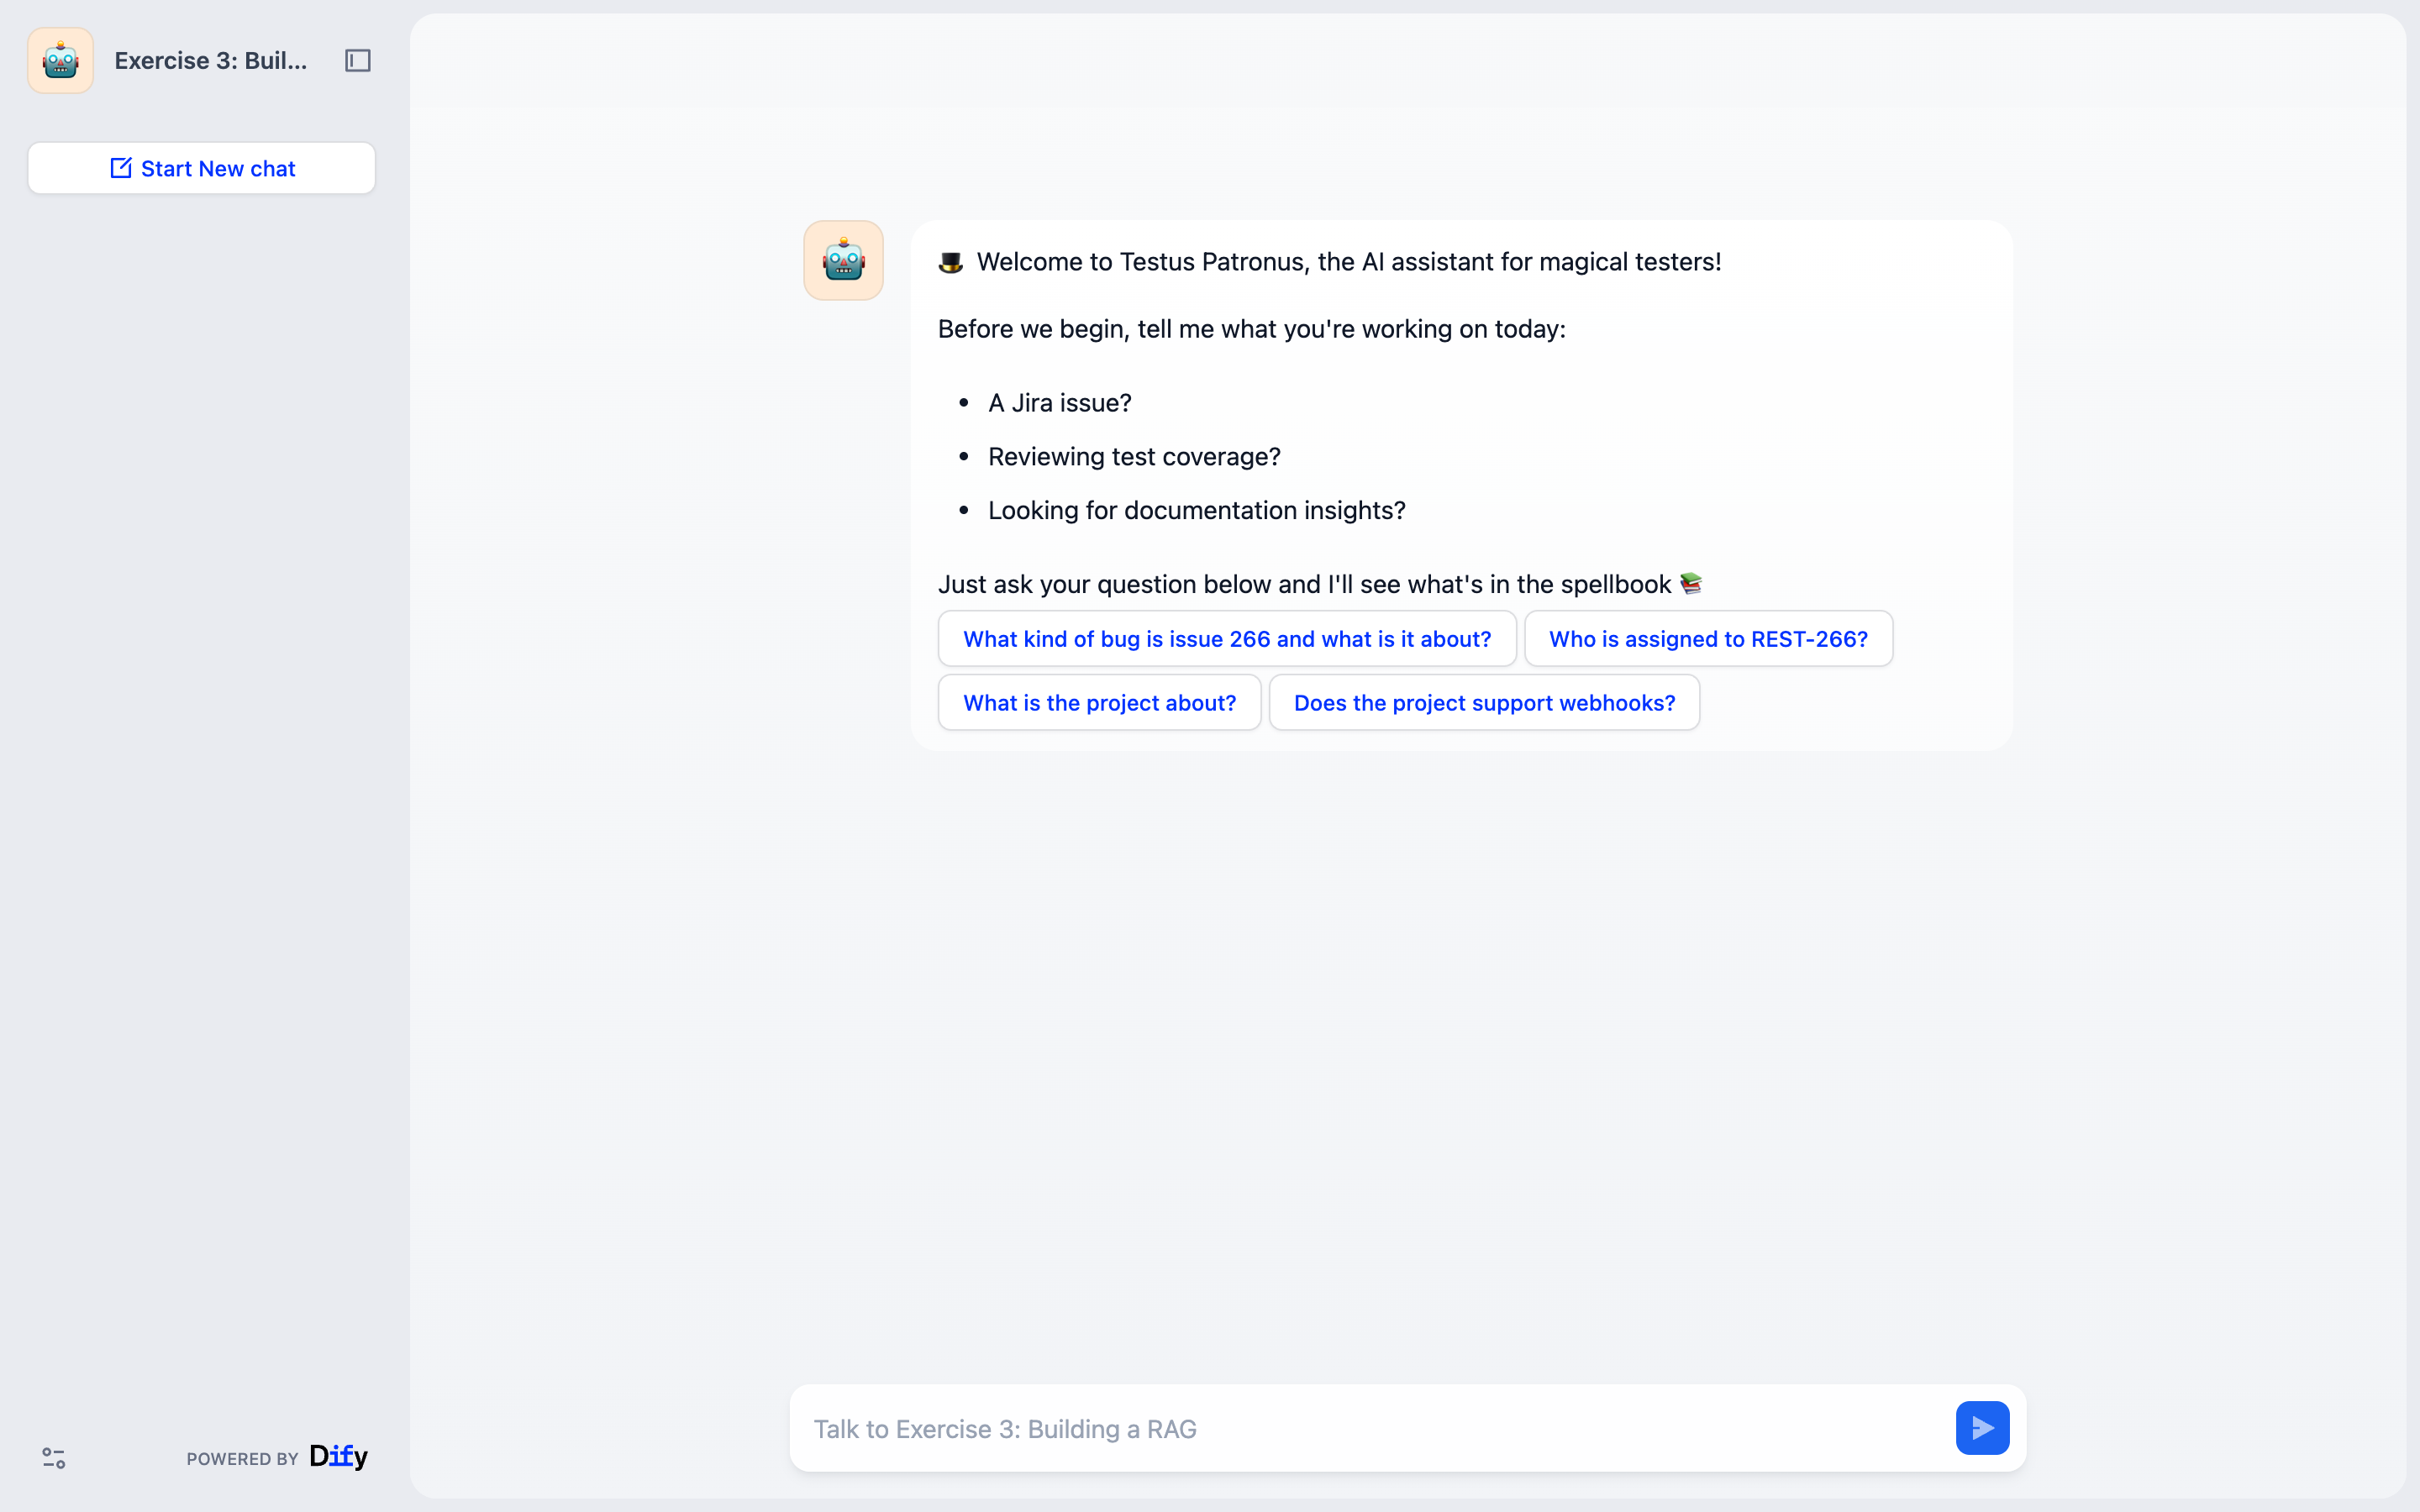
Click Features in the top bar and turn on Conversation Opener. Then hover the card, click Edit opener, paste the message below, and add the suggested questions as Opening Questions.
🎩 Welcome to Testus Patronus, the AI assistant for magical testers!

Before we begin, tell me what you're working on today:
- A Jira issue?
- Reviewing test coverage?
- Looking for documentation insights?

Just ask your question below and I'll see what's in the spellbook 📚
- What kind of bug is issue 266 and what is it about?
- Who is assigned to REST-266?
- What is the project about?
- Does the project support webhooks?
📝 Sample Queries
- What kind of bug is issue 266 and what is it about?
- Who is assigned to REST-266?
- What is the project about?
- Which issues are currently open?
- Does the project support webhooks?
- What features are planned for the next release?
- Who is assigned to REST-259?
- Summarize the technical documentation for the REST module.
🤔
Open Question: Are all the queries above answered properly by your chatbot? If not, why do you think that is? What could you improve in your knowledge base or prompt?
You'll learn more about troubleshooting and improving your chatbot's answers in Exercise 4: Advanced RAG!
🚀 Publishing Your Chatflow
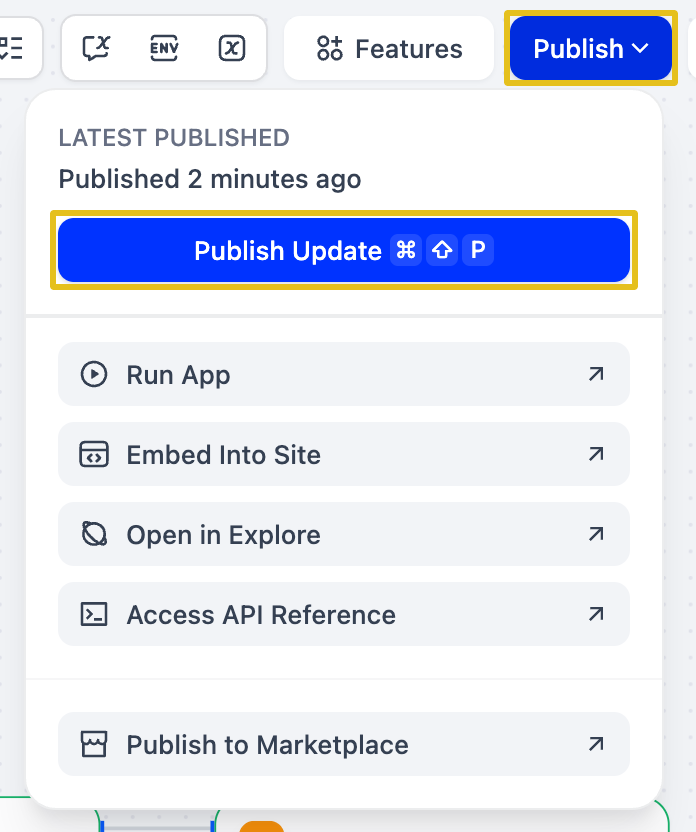
Click Publish in the top-right corner, then Publish Update.
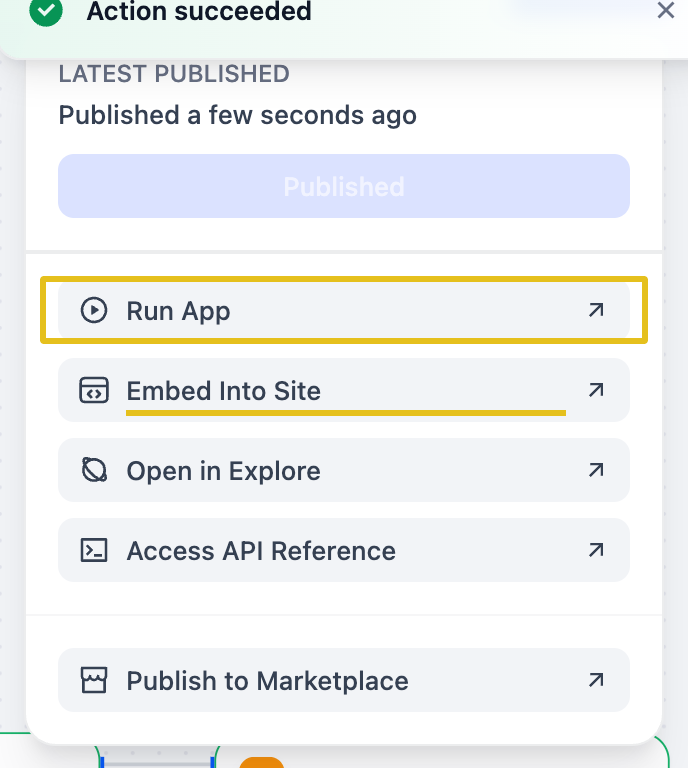
Once published, click Run App to open your chatbot as a web app.
Share the link with your team or test it in a new browser window. If you added a Conversation Opener, it greets users with your opening questions.
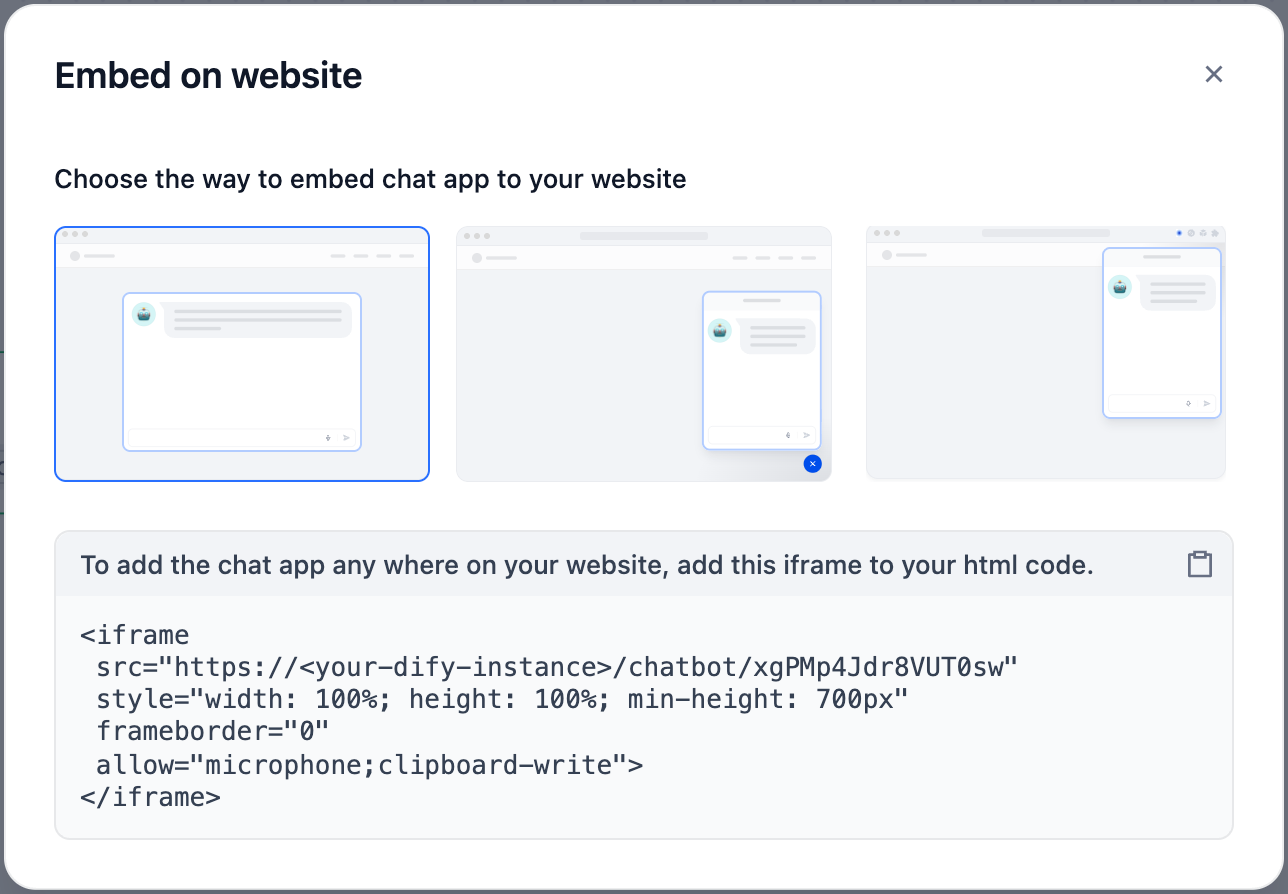
Optionally, click Embed Into Site to get an iframe or script snippet for your own website.
Tip: Test your published chatbot with the sample queries above to ensure everything works as expected!
Keep a version you can go back to
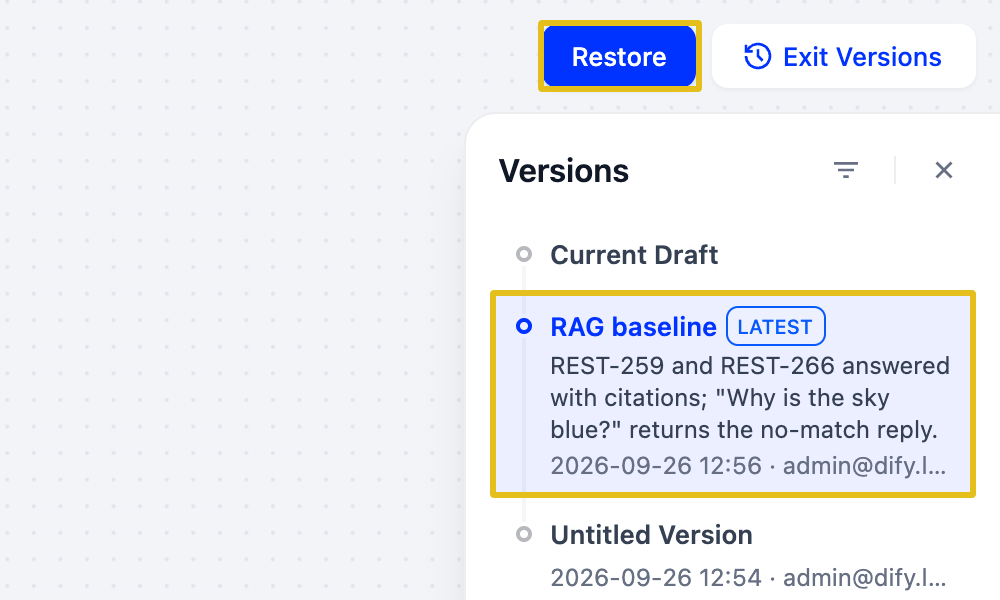
Each publish saves a snapshot in the version history, so you can experiment in Exercise 4 and still roll back:
- Publish only after the grounding checks in Step 4 and Step 5 pass.
- Click the clock icon at the far right of the top bar to open Versions.
- Open the ⋯ menu on the latest version, choose Edit Info, and give it a short title and release notes describing what you checked.
- Select a version to preview it. Restore copies it back into your draft.
🧩 Solution Download
⬇️ Download Exercise 3 Solution DSL
After importing the solution, open the Knowledge Retrieval node and select your own knowledge base: the one referenced in the file only exists on the instance it was exported from.
Ready to see your chatbot answer questions with real context? Move on to the next exercise to explore advanced prompting and evaluation!